Andrey Styskin
Andrey Styskin
Keenable partners with Baseten to make web search native to inference
Keenable partners with Baseten to make web search native to inference
Keenable partners with Baseten to make web search native to inference
Developers running on Baseten can now give their models access to the live web inside the same inference request. Keenable Search is available through Baseten Hosted Tools, with no separate key or harness to manage, and no custom agent loop to build.
It is our first step in a broader commitment: bringing better context management, quality and latency to web search as a native part of inference.
Baseten is our first inference-platform partner. Together, we’re working to make state-of-the-art web search faster, cheaper, and native to the model experience.
Developers running on Baseten can now give their models access to the live web inside the same inference request. Keenable Search is available through Baseten Hosted Tools, with no separate key or harness to manage, and no custom agent loop to build.
It is our first step in a broader commitment: bringing better context management, quality and latency to web search as a native part of inference.
Baseten is our first inference-platform partner. Together, we’re working to make state-of-the-art web search faster, cheaper, and native to the model experience.
Why should developers have to assemble web access?
You want your agents to solve your problems and along the way, plan, find information, check facts, and deliver a better answer. What you don’t want is the manual work that it takes: constantly prompting them, managing the context, figuring out snippet sizes, or even supporting one more tool with separate billing and unclear cost and tracking.
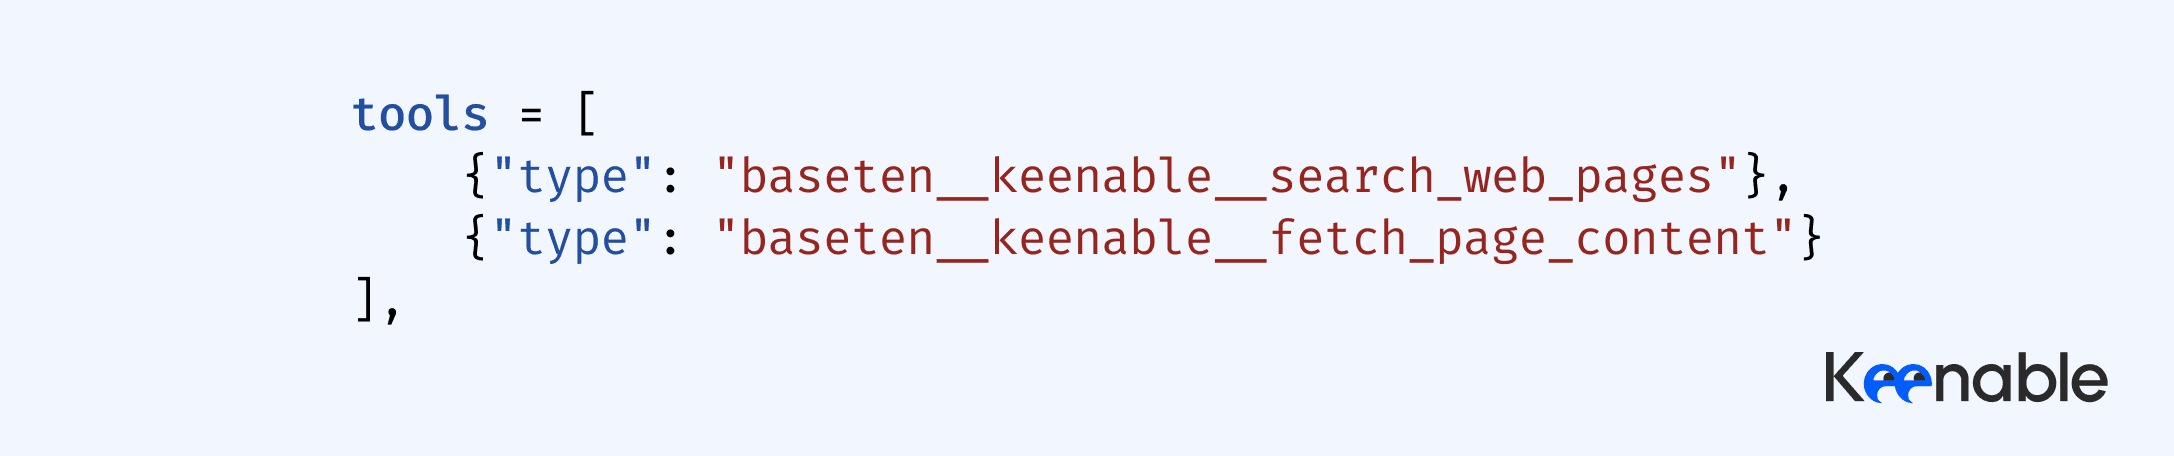
With this integration, you enable Keenable’s hosted web search and page-fetch tools in your Baseten request. Baseten handles tool execution and passes the retrieved content back to the model, so it can search, read, and continue reasoning within that request. Together with Baseten, we’ve aimed to bring better context management, quality and latency optimizations for web search, and this is only the starting point.
You build the agent. Web access is already there. As simple as it sounds:
Does simpler mean compromising on performance?
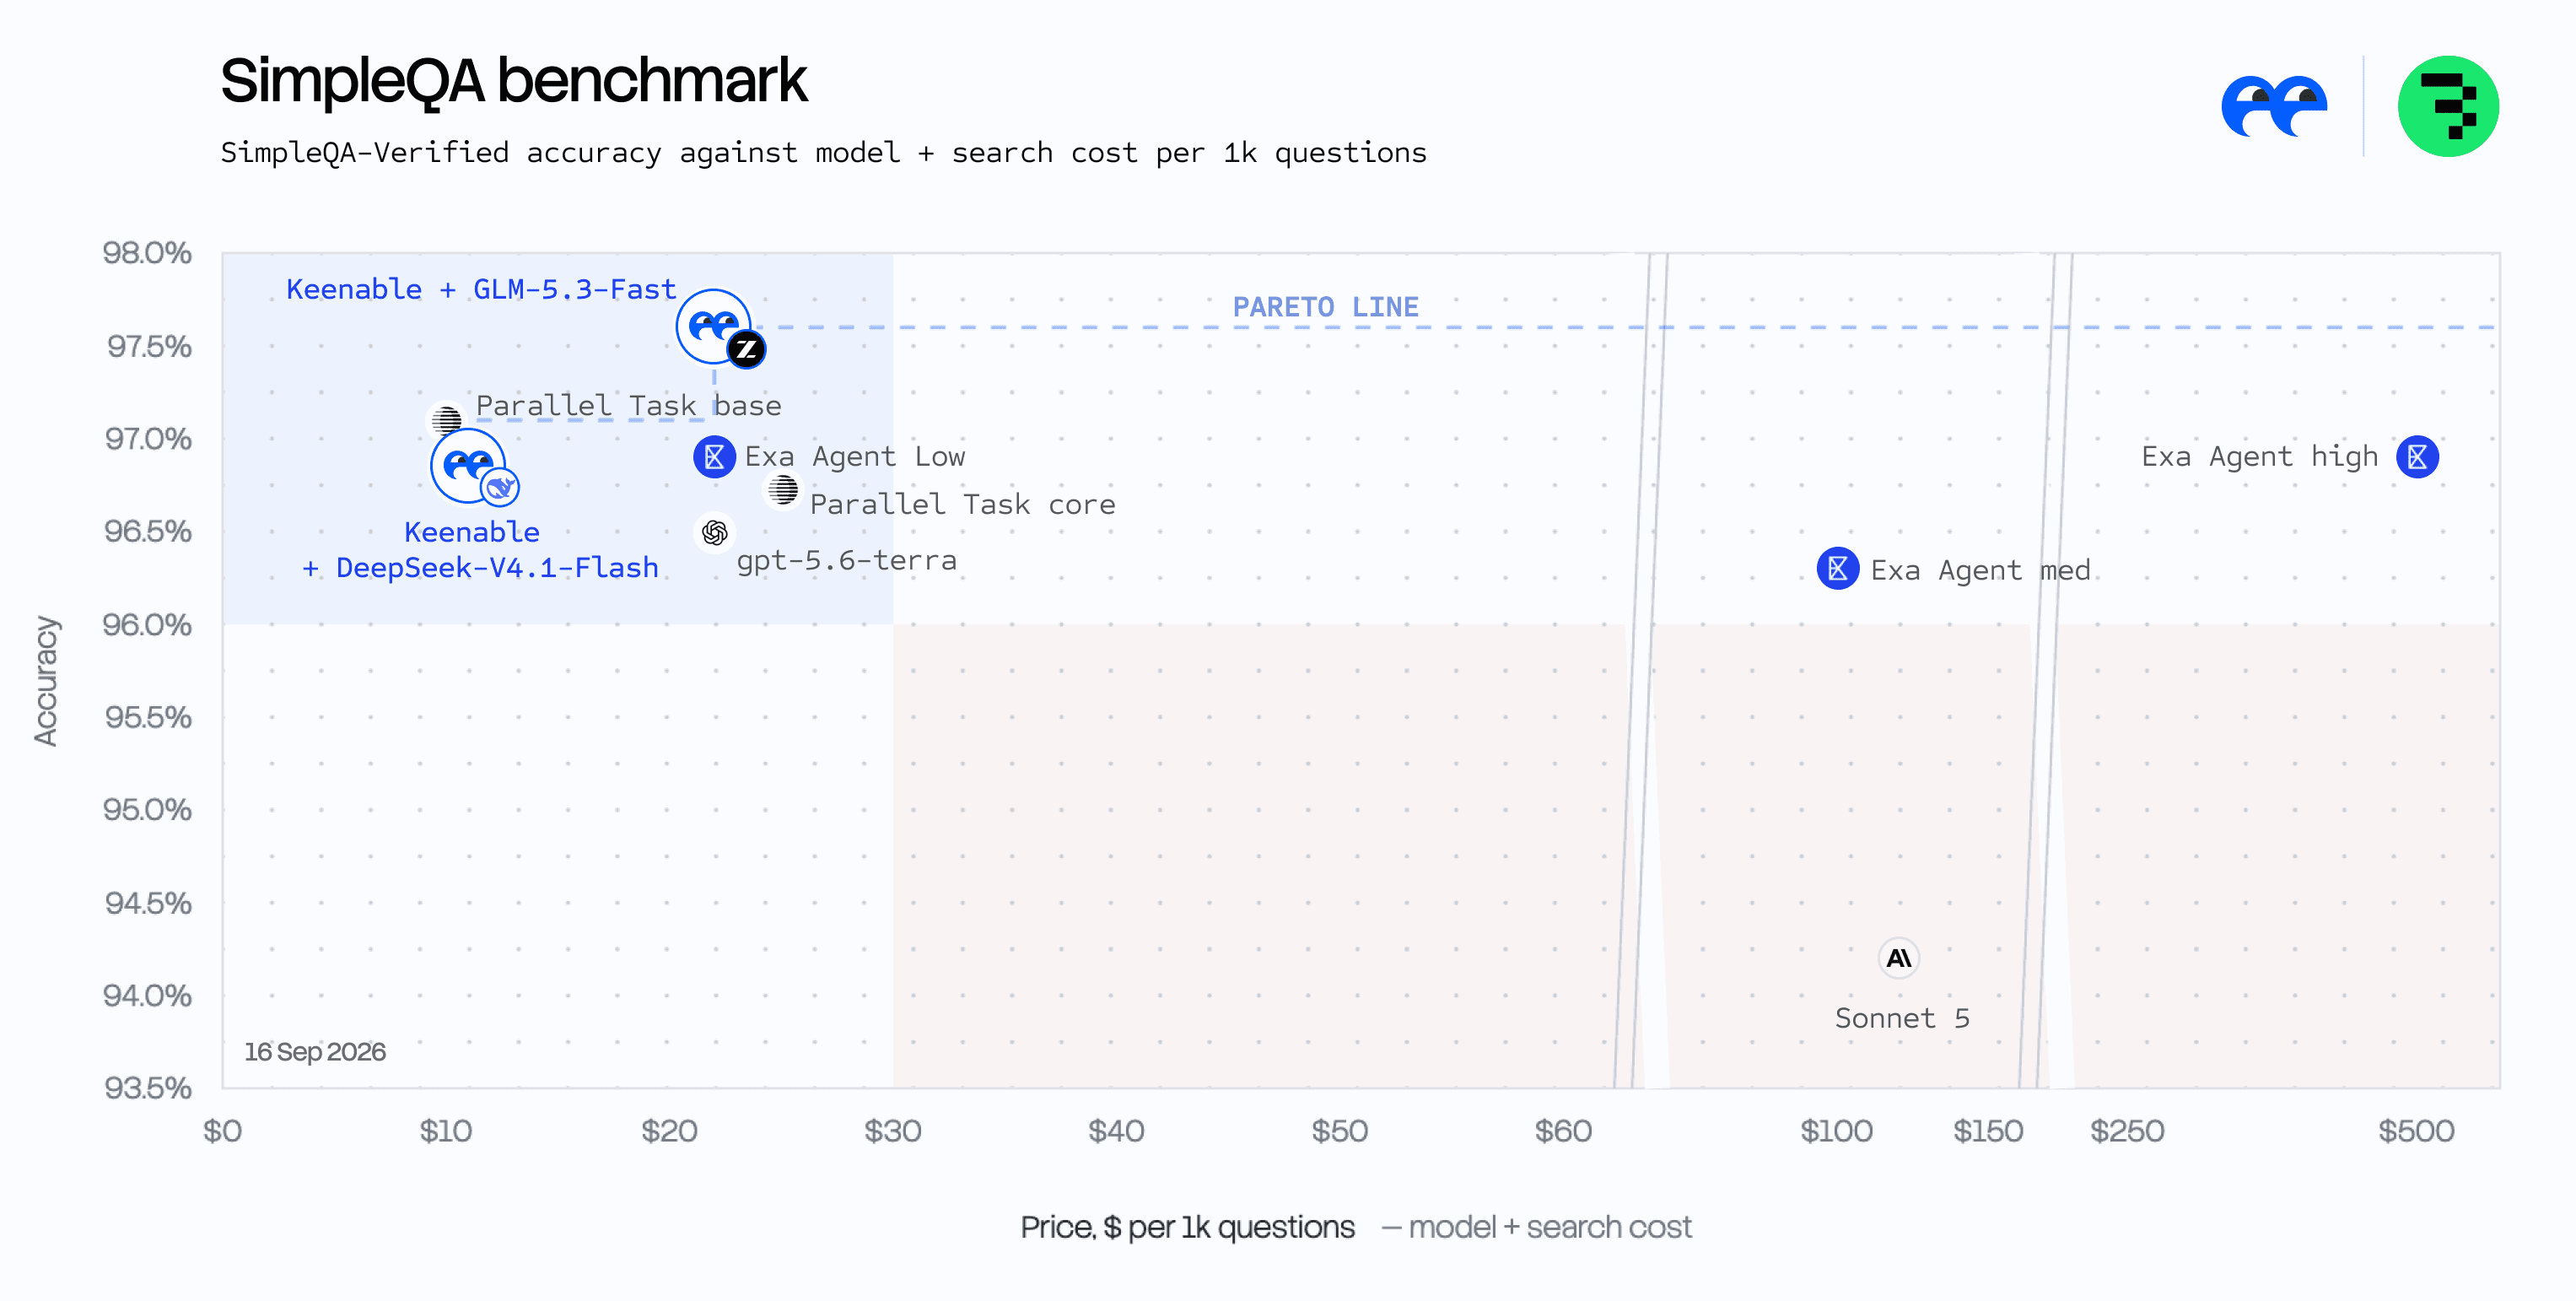
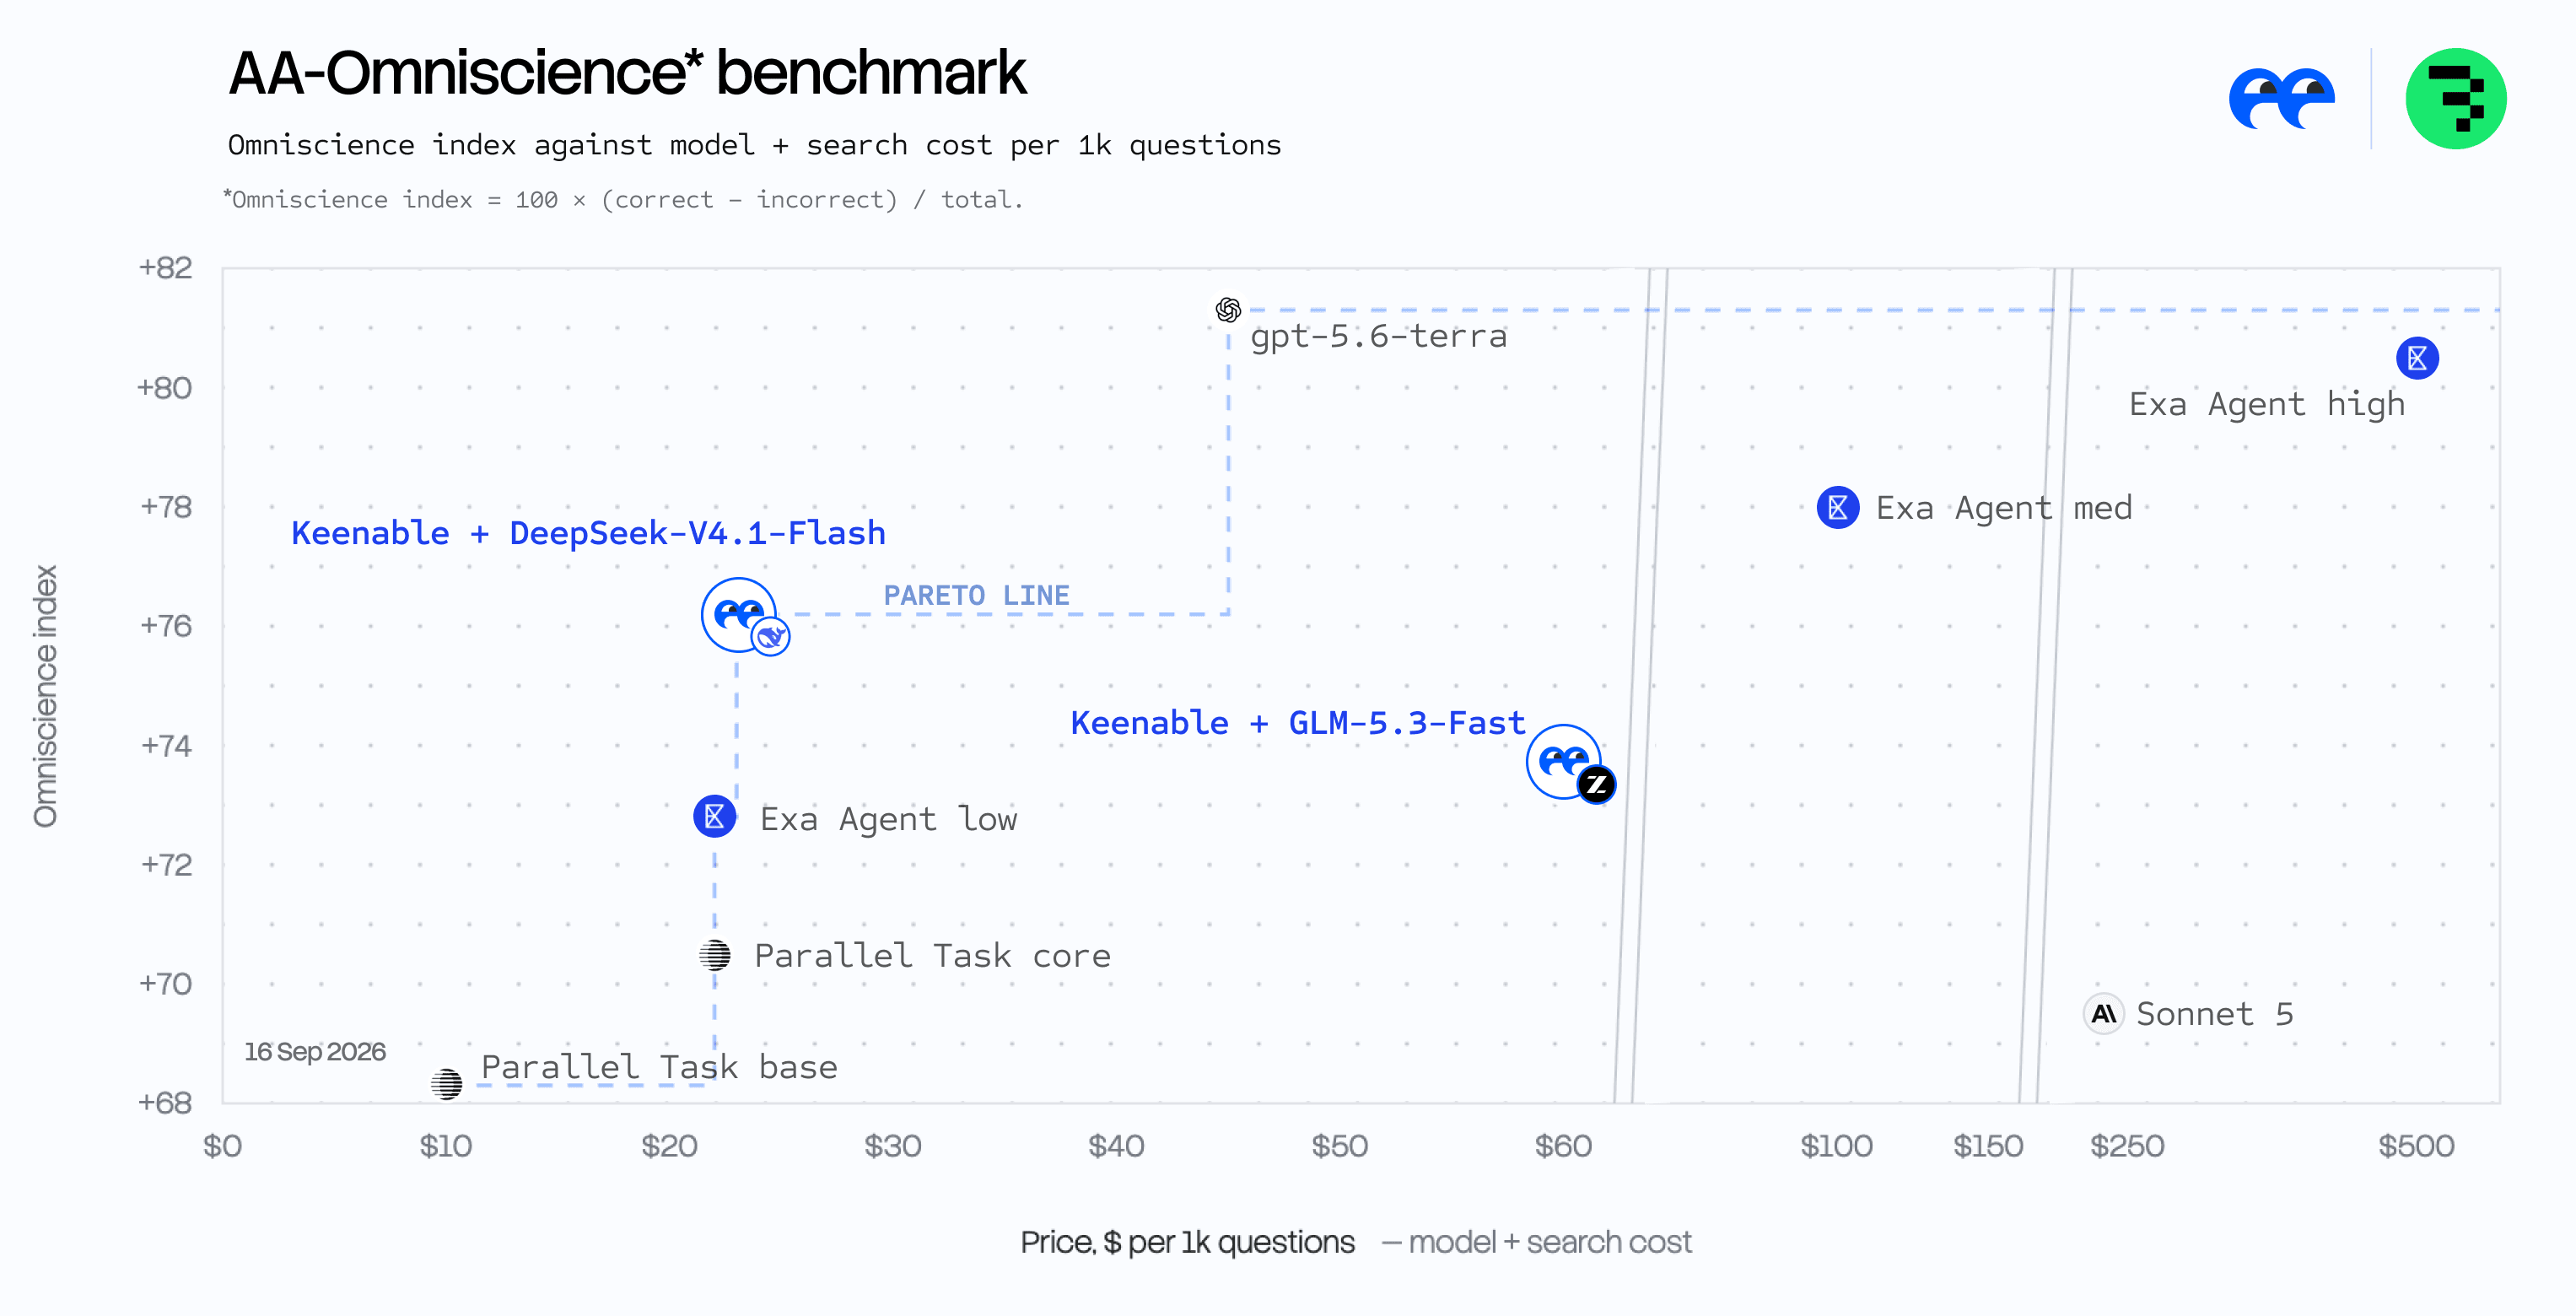
It shouldn’t. Native search needs to deliver on all three dimensions: quality, cost, and speed.
The comparison that matters is the complete task, not the performance of an individual search call. That means measuring answer quality, end-to-end latency, and total cost, including the tokens the model spends reading retrieved content.
Why is this just the beginning?
We want models to search more: to check an assumption instead of guessing, compare sources instead of stopping at the first result, and follow a useful lead before answering.
That becomes practical when search is fast, affordable, and built in. Developers shouldn’t have to choose between giving their models better access to knowledge and keeping their applications simple.
Web search should be a native capability of every model experience, on every inference platform instead of being another integration each team has to assemble.
Baseten is our first partner in making that happen, and improving context management, quality, and latency is what we’ll keep working on.
To get started, enable Keenable’s search and page-fetch tools through Baseten Hosted Tools.
Documentation: https://docs.keenable.ai/integrations/baseten
Why should developers have to assemble web access?
You want your agents to solve your problems and along the way, plan, find information, check facts, and deliver a better answer. What you don’t want is the manual work that it takes: constantly prompting them, managing the context, figuring out snippet sizes, or even supporting one more tool with separate billing and unclear cost and tracking.
With this integration, you enable Keenable’s hosted web search and page-fetch tools in your Baseten request. Baseten handles tool execution and passes the retrieved content back to the model, so it can search, read, and continue reasoning within that request. Together with Baseten, we’ve aimed to bring better context management, quality and latency optimizations for web search, and this is only the starting point.
You build the agent. Web access is already there. As simple as it sounds:
Does simpler mean compromising on performance?
It shouldn’t. Native search needs to deliver on all three dimensions: quality, cost, and speed.
The comparison that matters is the complete task, not the performance of an individual search call. That means measuring answer quality, end-to-end latency, and total cost, including the tokens the model spends reading retrieved content.
Why is this just the beginning?
We want models to search more: to check an assumption instead of guessing, compare sources instead of stopping at the first result, and follow a useful lead before answering.
That becomes practical when search is fast, affordable, and built in. Developers shouldn’t have to choose between giving their models better access to knowledge and keeping their applications simple.
Web search should be a native capability of every model experience, on every inference platform instead of being another integration each team has to assemble.
Baseten is our first partner in making that happen, and improving context management, quality, and latency is what we’ll keep working on.
To get started, enable Keenable’s search and page-fetch tools through Baseten Hosted Tools.
Documentation: https://docs.keenable.ai/integrations/baseten